
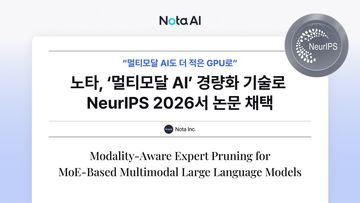
Nota, Multimodal AI GPU Memory Reduced by 47%
AI model optimization company Nota has developed a pruning technique specialized in the Mixture of Experts (MoE) structure for multimodal AI. The comp…
2026.10.01 by 배종인 기자
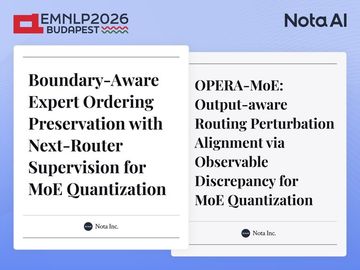
Nota, 2 MoE Quantization Papers Accepted at EMNLP 2026
AI model lightweight company Nota has secured acceptance of 2 papers on large language model optimization at EMNLP 2026. The company demonstrated that…
2026.08.25 by 배종인 기자
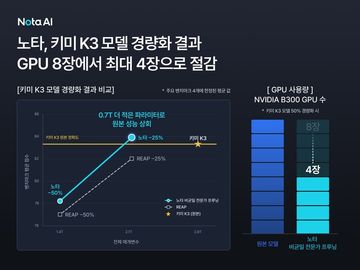
Nota, MoonShot AI 'Kimi K3' Lightweight Version…Nvidia B300 GPU Reduced from 8 to 4 Units
AI model optimization company Nota has lightweight-optimized MoonShot AI's 2.8 trillion parameter ultra-large AI model 'Kimi K3'. By applying propriet…
2026.08.06 by 배종인 기자
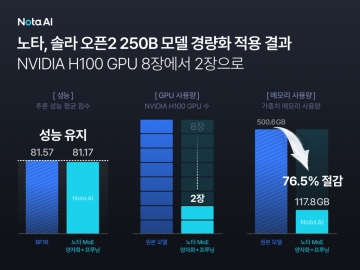
Nota Reduces AI Infrastructure Costs by Up to 76.5%... Unveils Lightweight Model Dedicated to 'Solar Open2'
Nota, a specialized AI model optimization company, has unveiled a lightweight version of Upstage's government-backed AI foundation model Solar Open2. …
2026.07.27 by 배종인 기자
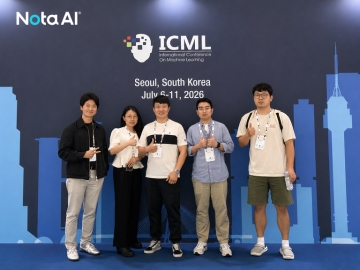
NOTA Takes 3rd Place at ICML 2026 Challenge… Qwen Inference Optimization Technology Validated
AI model compression company Nota AI achieved 3rd place in the 'Efficient Qwen Competition' at the International Conference on Machine Learning ICML 2…
2026.07.13 by 배종인 기자
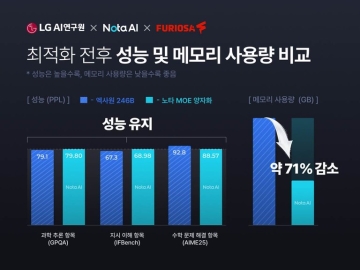
Nota Successfully Optimizes LG K-ExaOne 236B on Domestic NPU
Nota has successfully optimized LG's K-ExaOne 236B on Furioxa AI's datacenter NPU. This achievement, which reduced model size by 71% while maintaining…
2026.06.30 by 배종인 기자
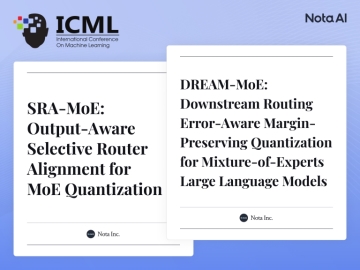
NOTA Presents Two MoE Quantization Research Papers at ICML 2026 Workshop
Nota, an AI model optimization and lightweight technology company, will present two research papers on MoE model quantization at the ICML 2026 AdaptFM…
2026.06.11 by 명세환 기자
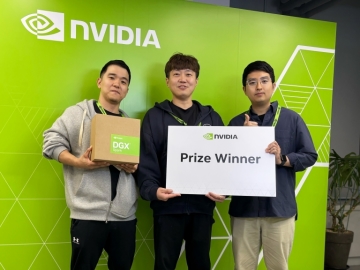
Nota Takes First Place Overall at NVIDIA's 'Nemotron Hackathon'... Demonstrates Potential for Data-Centric AI Optimization
Nota achieved first place overall at the NVIDIA Nemotron Hackathon. Nota recorded first place in Track C by improving quantization performance based o…
2026.04.27 by 배종인 기자
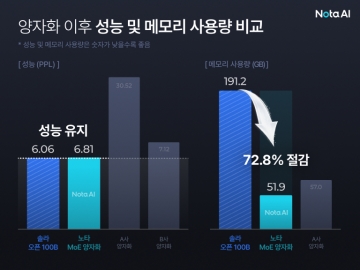
Nota Unveils Upstage's "Solar Open 100B" Quantization Model, Increasing Weight Memory from 191.2GB to 51.9GB
As quantization competition to reduce GPU memory burden—a key variable in AI model operating costs—spreads to large language models (LLMs), Nota has r…
2026.03.05 by 배종인 기자