

ElevenLabs Launches TTS Models 'Eleven v4' and 'v4 Turbo'
 Published2026.10.01 09:08
Co-founder and Chief Technology Officer Piotr Dabkowski stated, "Based on a completely new architecture, it has broad emotional expression and fine-grained control capabilities, and was designed with low-latency applications in mind, providing the same expressive power in the conversational agent field."
Users can specify expression style in natural language or fine-tune utterance style and acoustic effects using inline tags such as '[laughter]' and '[light rain].'
Speaker consistency has improved compared to the previous Eleven v3 generation, and performance in implementing multi-party conversations has also been enhanced.
Supported languages have increased from 70 to over 90, with notably improved performance in Japanese, Mandarin Chinese, and Brazilian Portuguese.
It also provides functionality to switch language and intonation while maintaining the pitch and timbre of the original voice.
It can be applied to conversational agents in diverse industries including healthcare, finance, and gaming, and is optimized as a single system with ElevenLabs' conversational agent platform 'ElevenAgents.'
In terms of security, it complies with global regulations including the EU General Data Protection Regulation (GDPR), the US Health Insurance Portability and Accountability Act (HIPAA), SOC 2, and PCI, with voice cloning utilizing 'Voice CAPTCHA' authentication and 'No-Go Voices' safeguards that block major public voice replications.
Meanwhile, cumulative revenue generated by creators who have registered voices in ElevenLabs' 'Voice Library' has exceeded $22 million (approximately 30 billion Korean won) to date.
Comments
Related news

ElevenLabs Unveils AI Dubbing Model 'Dubbing v2'…Enhanced Emotional Expression Across 92 Languages
ElevenLabs, an AI audio specialist company, has unveiled a next-generation AI dubbing model that preserves the emotion and expression of the original voice. The technology aims to improve multilingual dubbing quality amid growing demand for content localization.
2026.08.10by 배종인 기자

ElevenLabs, AI voice restoration, voice cloning, PVC, TTS, corporate heritage, voice AI, audio AI, content localization
AI audio company ElevenLabs is expanding its AI voice restoration service across various industry sectors including enterprises, media, and education.
2026.08.18by 배종인 기자
MatrixCloud builds next-generation AI contact center with ElevenAgents adoption
CCaaS specialist MatrixCloud has adopted ElevenLabs' AI voice agent platform ElevenAgents to build a next-generation AI contact center. By managing STT, LLM, and TTS in a single integrated workflow, the company has eliminated existing response delays of over 3 seconds and reduced development and operational complexity. The two companies plan to expand joint marketing and technical collaboration with the goal of entering the global AICC market.
2026.09.01by 배종인 기자
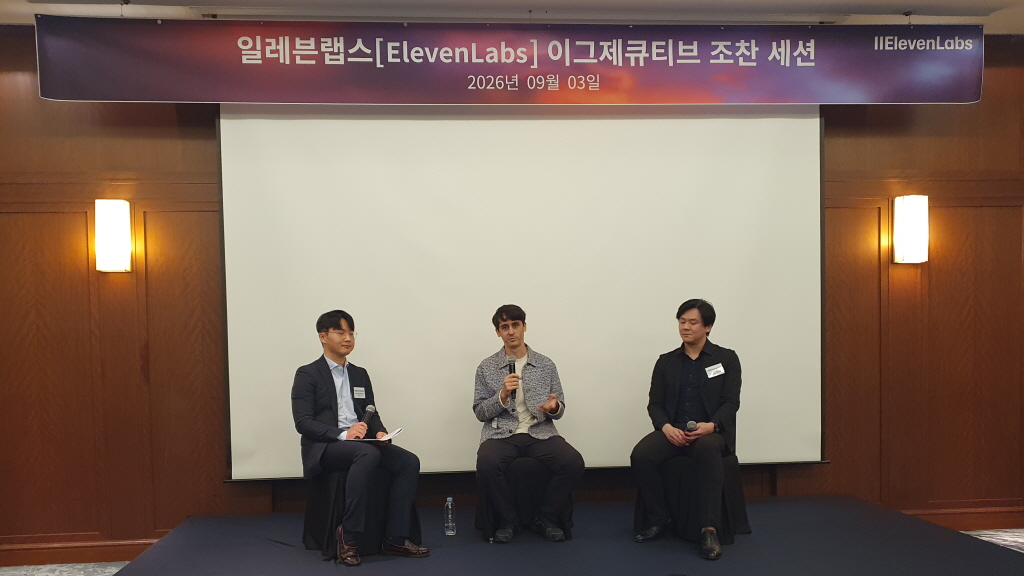
ElevenLabs, "Voice AI Evolving into New Enterprise Operating Platform"
Generative AI is evolving beyond simple assistants into agents performing actual business tasks, with voice AI in particular having already entered the commercialization stage in customer service and content localization sectors. ElevenLabs recorded ARR of $600 million and corporate valuation of $11 billion, with over 2 million voice agents deployed, utilized by 60% of Fortune 500 companies. Growth in the APAC region is particularly pronounced, with domestic adoption expanding among companies such as NH Nonghyup, Shinhan, LG U+, and Caring. Experts emphasized that Korean enterprises need rapid adoption expansion, clear use case establishment, and performance validation projects within 90 days to secure competitiveness.
2026.09.03by 배종인 기자
ElevenLabs Appoints Ashley Kramer as New CRO
Voice AI startup ElevenLabs has appointed Ashley Kramer, former head of enterprise sales at OpenAI, as its new Chief Revenue Officer. At a time when the company has surpassed $600 million in annual recurring revenue (ARR) and achieved over 55% in enterprise revenue, the company is bringing in an executive dedicated to managing the global revenue organization to accelerate business expansion focused on enterprise customers. Currently, thousands of companies, including over 80% of Fortune 500 enterprises, are utilizing the platform.
2026.09.08by 배종인 기자